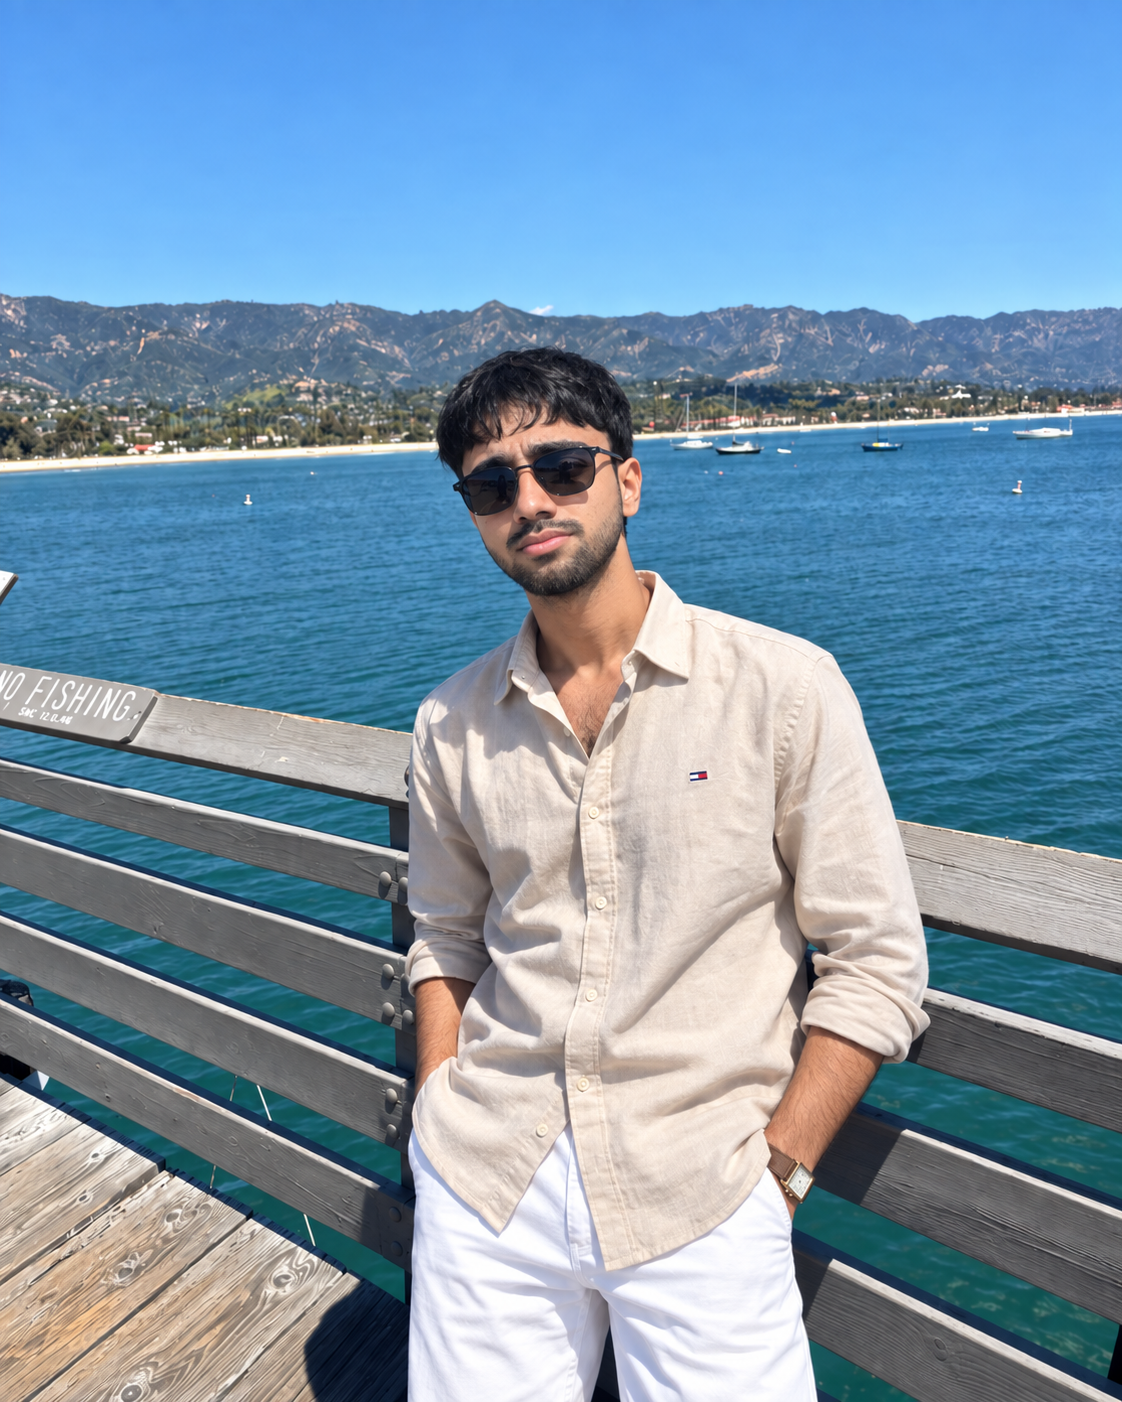
Daud Ibrahim Hassan
Empirical AI Safety Researcher
I study how AI systems fail: what they report, what monitors miss, and whether information they should forget can still be recovered.
BRAC University · BSc Computer Science and Engineering
Current research
BRAC University · Undergraduate thesis in progress
The Unlearning Illusion
The Unlearning Illusion: A Red-Teaming Framework for Probing the Reversibility of Machine Unlearning in Large Language Models.
I’m developing adversarial recovery tests to distinguish apparent forgetting from genuine removal. The question is whether information targeted for removal remains recoverable under red-team probing. I build Python experiment and analysis pipelines for systematic comparison.
DeepLearning.AI · Course Tester · August 2026 - Present
Research engineering beyond the paper
I test pre-release AI/ML exercises, hands-on labs and learning content. I reproduce failures, check edge cases and provide structured technical feedback before release.
My open-source work also includes four merged upstream fixes across Grafana and Crawl4AI: template-variable interpolation, a panel-editor crash, Markdown structure and a WSL browser hang.
Independent AI safety research · 2026 - Present
Monitor Calibration Transport
Monitor Calibration Transport: Evaluating AI Safety Monitor Reliability Across Models and Distribution Shifts.
I investigate whether safety monitors calibrated on one model or task remain calibrated across models, task distributions and deployment-like shifts. The focus is false-negative risk, transportability and the reliability of monitoring signals.
Papers
AI safety, evaluation and reproducible research.
Balanced but Misleading: Can Epistemic Scores Miss Decision-Changing Omissions? ↗
Daud Ibrahim Hassan and Elvina Chow · Independent Researchers · With Apart Research
A six-family development study separating briefing balance, qualification evidence and abstention semantics. The findings support a benchmark-specific false-rejection diagnosis, with omission counts sensitive to task conversion.
Does Resetting One Agent Break Mutual Approval?
Daud Ibrahim Hassan, Govardhan Reddy, Salar Humayun Taimuri, Chandani and Emi Eggleton
A Matched History-Reset Study of LLM Agent Pairs
False Containment: Measuring the Evidence Required to Verify Autonomous AI Incident Resolution ↗
Daud Ibrahim Hassan, Govardhan Reddy, Soumya Parthasarathy, Disha Singha and Taemin Park · 2026 · Apart Research AI Incident Response Sprint
A research project about how much evidence is actually needed before claiming that an autonomous AI incident has been resolved.
Daud Ibrahim Hassan, Deniz Chen, and Soumya Parthasarathy · 2026 · Apart Research Digital Minds Research Sprint
A study of whether language models accurately report what they did when structured provenance and tool-use records are available.
MarkLens: Measuring Cross-Manager Valuation Dispersion in Private Credit at Scale ↗
Daud Ibrahim Hassan · 2026 · Independent preprint
A reproducible SEC EDGAR study of cross-manager private-credit valuation differences at scale.
Monitor Calibration Transport: Evaluating AI Safety Monitor Reliability Across Models and Distribution Shifts
Daud Ibrahim Hassan · 2026 · Independent AI safety research
A study of whether safety monitors calibrated on one model or task remain reliable when the model, task or deployment conditions change.
Planned research · Paper link not yet available
Featured research outputs
Daud Ibrahim Hassan and Elvina Chow · Independent Researchers · With Apart Research
Balanced but Misleading: Can Epistemic Scores Miss Decision-Changing Omissions?
A six-family development study separating briefing balance, qualification evidence and abstention semantics. Across 930 valid receiver responses, 19 selected neither despite a qualifying option; all 69 valid full-evidence controls were correct.
Omission counts are sensitive to task conversion. The findings support a benchmark-specific false-rejection diagnosis, not held-out validation, a general promotional effect or failure of broader epistemic scores.
Daud Ibrahim Hassan, Govardhan Reddy, Salar Humayun Taimuri, Chandani and Emi Eggleton
Does Resetting One Agent Break Mutual Approval?
A Matched History-Reset Study of LLM Agent Pairs
Daud Ibrahim Hassan, Govardhan Reddy, Soumya Parthasarathy, Disha Singha and Taemin Park · 2026 · Apart Research AI Incident Response Sprint
False Containment
I built the evaluation pipeline, verifier runs and evidence-ablation conditions for testing AI incident-resolution claims.
False Containment Rate: unresolved incidents incorrectly classified as resolved under incomplete telemetry.
Daud Ibrahim Hassan, Deniz Chen and Soumya Parthasarathy · 2026 · Apart Research Digital Minds Research Sprint
When the Record and the Report Diverge
I built and ran the evaluation pipeline, checking model self-reports against deterministic tool-execution logs.
Haiku exact access-report fidelity: 96.5% → 57.6%. Free-form notes and Qwen retained 100% fidelity in this evaluation.
Daud Ibrahim Hassan · 2026 · Independent preprint
MarkLens
I built a reproducible SEC EDGAR pipeline that extracted 251,350 position-level holdings and constructed 2,163 same-loan, same-date cross-manager facility-quarters.
Matching was validated at 97.6% precision and 93.5% recall. Cross-manager valuation disagreement was 1.41 points of par, with a 95% confidence interval of 1.13-1.74. The code, panel dataset, analysis and Observatory were released with a DOI.
Research programs
Research Facilitator · October 2026–Present · Remote

Mercial Research Fellowship
Facilitating “How should we handle research done by AIs?” for the November cohort. The project investigates how to assess AI-generated research through source verification, reproducibility and whether conclusions follow from the evidence.
Responsibilities include interviewing prospective fellows, helping scope research questions, and supporting investigation and the final write-up.
Research Incubator Participant · Remote · 2026 - Present
AI Safety Camp
Machine unlearning research: reproducible adversarial evaluation protocols, Python analysis pipelines and recovery testing.
I test whether information targeted for removal remains recoverable under adversarial probing.
Apart Research · September 2026 · Completed
AI Incident Response Sprint
False Containment: an empirical study of what evidence is sufficient to verify autonomous AI incident resolution.
My work covered the end-to-end evaluation pipeline, verifier runs, evidence ablation and ground-truth comparison. The publication author list remains to be verified.
AI Safety Navigator (Facilitator) · October 2026–Present · Remote
Lens Academy
Facilitate discussions on AI risk, evaluation, reliability and safety, helping participants examine evidence, question assumptions and reason through competing arguments.
Assigned to the next AI Risk Fundamentals cycle and the facilitator cover bench.
Apart Research · August 2026
Digital Minds Research Sprint
Co-authored When the Record and the Report Diverge with Deniz Chen and Soumya Parthasarathy.
I built the evaluation pipeline and executed all 216 runs. Deniz Chen supported results calibration and Soumya Parthasarathy supported documentation.
AI Safety Technical Contributor · September 2026–Present · Remote
EquiStamp
Contributed to multiple confidential AI safety projects, including evaluation pipelines, safety testing and pipeline tests. Project details are not public.

Interested in research or collaboration?
I’d love to hear about your research or collaboration idea.
Dhaka, Bangladesh